AI Transcription Accuracy for Field Sales Environments
Field accuracy depends on acoustic conditions and capture timing, not vendor benchmarks.
AI transcription accuracy for field sales depends on whether a system works where reps sell. Noise, overlapping speech, mobile recording, and delayed capture change both what gets transcribed and what reaches the CRM. Sales leaders need to evaluate field accuracy as an architectural and workflow requirement, rather than treating a vendor’s headline number as evidence of readiness.
Why vendor accuracy benchmarks don't describe the conditions where field reps actually sell
The accuracy number in a vendor’s sales deck describes a different recording environment from the one a rep encounters in a customer’s warehouse. Benchmark audio is usually clean English with a single speaker and little background noise. On a manufacturing floor, in a hospital corridor, or at a customer site, none of that is guaranteed. The benchmark may be valid under its test conditions, but those conditions limit what the result can establish. The measurement goes wrong when teams expect a result from a controlled test to hold up in the field.
The standard measure also leaves out an important distinction. Word Error Rate, or WER, counts substitutions, insertions, and deletions equally, without distinguishing their importance to a sales conversation. A transcript can therefore score well while mishearing a customer’s name, a price, or a next-step commitment. Those errors have different consequences from a dropped filler word, even when the metric treats them alike. AssemblyAI’s 2026 accuracy guide identifies a shift toward semantic WER and “critical-word accuracy” in voice agent applications because raw WER can conceal these high-stakes failures.
Differences between models narrow on real-world audio when sound quality becomes the bottleneck. If a human must strain to hear a passage, AI is likely to get it wrong too. That makes a model’s position on a leaderboard less informative than its performance on the audio a team actually produces. A field test must check both whether the words can be heard in the recording and whether the details that matter to a sale make it into the transcript.
The four field conditions that reliably break transcription accuracy
Ambient noise is the first recurring source of failure. Machinery, HVAC systems, public address systems, vehicles, and background conversation compete with the speech being captured. Even the sounds of typing and paper can get in the way, and speech gets harder to capture when the microphone is farther away. These are ordinary working conditions. A tool tested only on clear speech has not demonstrated how it handles the acoustic interference present at customer sites.
Overlapping speakers create a different kind of ambiguity. Fast turn-taking and crosstalk can cause words from two people to merge into one sentence, produce incoherent fragments, or attach a statement to the wrong speaker. Group discussions are especially vulnerable to these errors. For sales teams, speaker attribution is part of the information being captured, because a multi-stakeholder conversation contains more than a sequence of words. Recognizing the words without preserving who said them leaves an incomplete account.
Accented and non-native English can differ in ways that clean English benchmarks may leave out. Some regional accents consistently produce lower accuracy when a model misinterprets unfamiliar phonetic patterns. An evaluation limited to a successful test with one rep or one customer leaves a gap in coverage of performance across regions.
Compressed or mobile audio is a fourth source of trouble. Phone microphones, in-car recording, and unstable connections are different from the recording setup that tools built for offices expect. Speech recognition tuned for road noise, HVAC systems, and restaurant conversation meets a need that comes with working in the field. Generic recognition can fail under those conditions. Because these four factors can compound one another, a regional accent captured in a noisy car is a different test from either accented speech or road noise in isolation.
Why the recording approach most tools assume creates its own additional problems in the field
Poor audio is only part of the mismatch. The assumption that reps can record every useful customer interaction overlooks consent constraints and the relationship dynamics of complex B2B selling. Buyers can become more guarded when a recording is present, reducing informal intelligence-sharing and weakening the collaborative exchange. Even better transcription cannot capture what a buyer never said.
Some of the most useful field intelligence also falls outside a recordable meeting structure. Sidebar conversations, parking lot debriefs with internal champions, and casual check-ins at customer sites can bring out key facts about a deal. These exchanges do not necessarily resemble scheduled calls with a defined beginning and end. A system built around recordings of whole meetings thus covers only part of the rep’s working day.
Field reps often conduct several customer meetings before reconstructing details and updating the CRM hours later, sometimes in the evening. By then, recall has deteriorated. Forgotten details, inaccurate recollection, incomplete accounts of multi-stakeholder discussions, and inconsistent entry all reduce the quality of the resulting record. Even a perfect transcript of that late summary cannot bring back a commitment the rep has already forgotten.
Managers cannot trust weak pipeline data for forecasting, and revenue operations needs better data for analytics. Marketing cannot reliably tell what influenced the pipeline, and executive leadership has little insight into how reps are doing in the field. Coaching also depends on the quality of the information available. Improving the microphone alone cannot ensure reliable information reaches the organization, because the capture method and its timing also shape that information.
What the architecture of a field-ready transcription system actually requires
The lesson for vendor evaluation is to ask about field capability as a connected set of requirements. Speech recognition must be tuned for the acoustic environments where reps work, including cars, restaurants, and customer sites. Acoustic models trained on field environments differ from models trained on quiet office conditions in their training data. A vendor conversation should establish how the system addresses road noise, HVAC systems, and background speech rather than accepting a general claim of noise tolerance.
Sales vocabulary is a separate requirement from acoustic robustness. Reps use product names, competitor terms, and industry jargon that consumer voice tools can misrecognize even when the audio is clear. Domain-tuned language models address that vocabulary without requiring vocabulary uploads. A tool that gets everyday conversation right may still get the terms a sales team uses wrong.
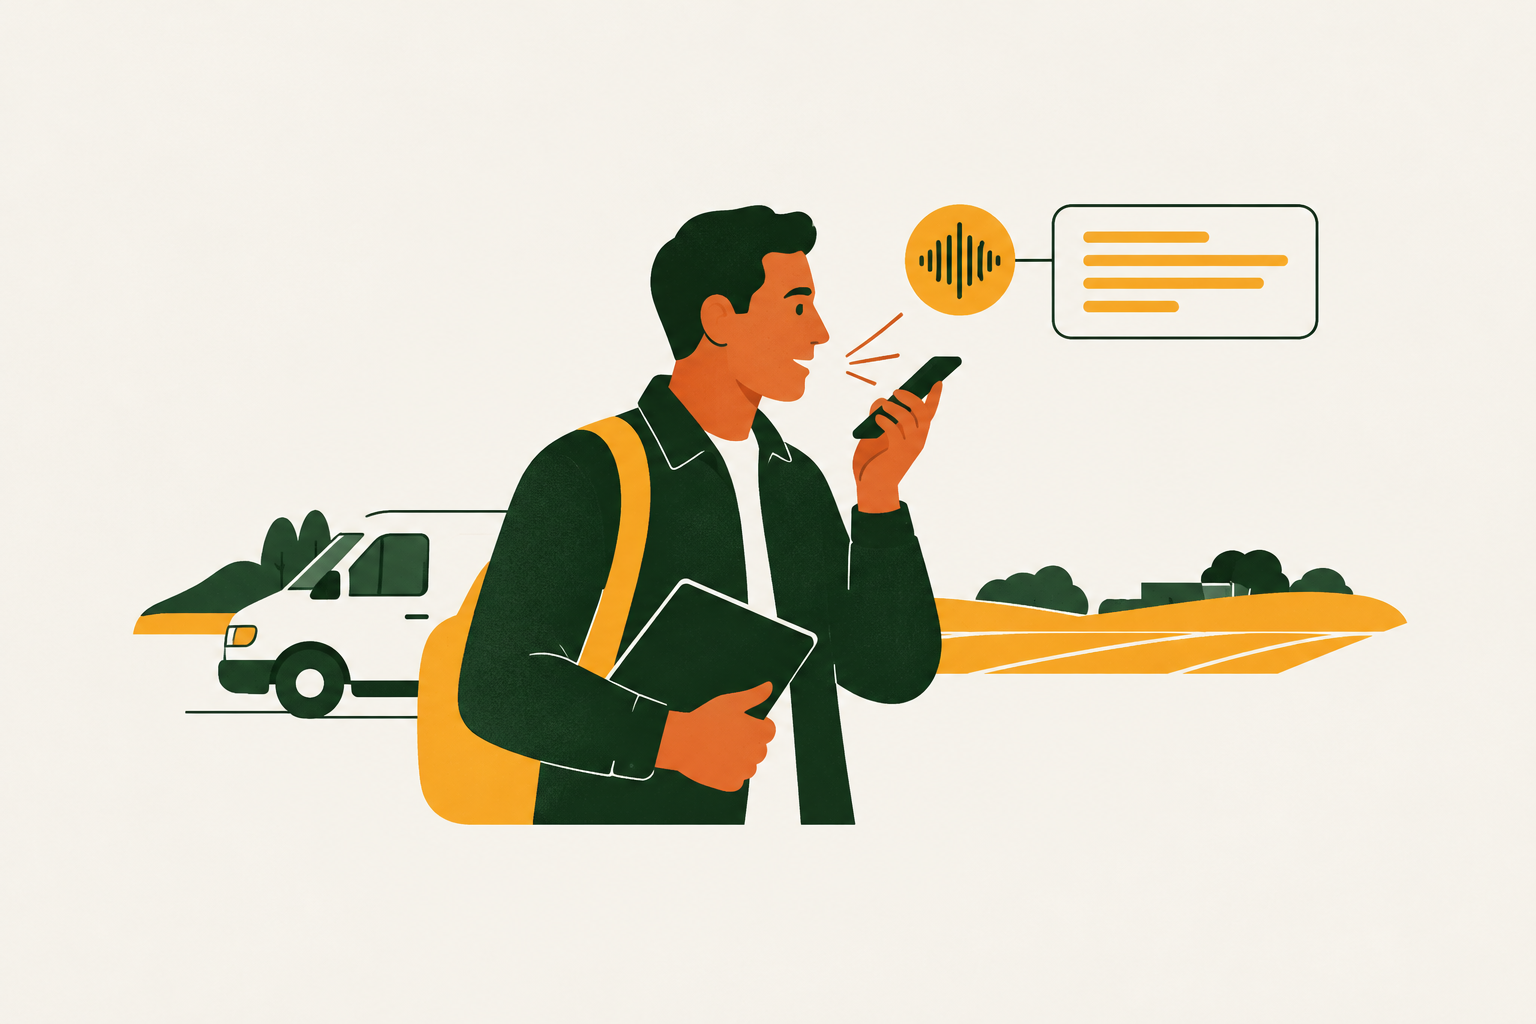
Capture must also fit the period immediately after an interaction. Field professionals have a brief window when recall is highest and cognitive load is manageable, making voice-first debriefing a better fit than a form completed hours later. A spoken summary can capture more accurate and complete detail, while its conversational format elicits information beyond structured fields. Timing is part of the design requirement. A tool that makes capture possible but leaves it until the evening still relies on deteriorated recall.
Agentic CRM integration must recognize that “she wants to move forward with a pilot” indicates stage advancement, while “send the proposal by Friday” requires a task. Without that intent layer, spoken words remain separate from the work they describe. Mobile-first design and offline capability complete the requirement set because reps work from phones and encounter connectivity gaps.
How to run a valid accuracy test before committing to a tool
A team running a pilot should use audio from the field. The material should represent the hardest conditions the team regularly encounters, including a noisy customer site, a multi-stakeholder meeting, a rep with a regional accent, and an in-car summary. These are the working inputs the tool must handle. Run that material through each tool at least three times before choosing one, because results can change from run to run. A single successful result is not enough to establish dependable behavior.
Create a human-verified “gold” transcript before comparing the outputs. That reference provides a baseline independent of the tool’s own confidence score. The team should compare WER and also check critical-word accuracy. Customer names, numbers, commitments, and competitor mentions need a closer look than filler words because the sales team needs those details accurately transcribed to use the transcript in its workflow.
The pilot should also include low-bandwidth and offline conditions. Optimal mobile connectivity does not represent the full field environment, so testing only under that condition leaves a central requirement unanswered. Connectivity gaps belong in the core test. The same evaluation should establish whether the system delivers the capture and interpretation capabilities already required, rather than stopping at the readability of its transcript. This keeps the decision tied to the information that reaches the CRM.
What purpose-built field tools do differently, and where to position conversation intelligence in the stack
Gong and Chorus handle post-call analysis for inside sales environments, where reps conduct calls at a desk. That is a useful capability in its intended setting. It does not establish suitability for the acoustics, connectivity, and CRM-update workflows of reps moving through warehouses or customer offices.
Purpose-built field platforms change the point and method of capture. They use voice debriefs instead of relying on live customer recordings, bring field-trained acoustic models and sales vocabulary together, and have offline capability so reps can work on the move. Agentic CRM routing then connects the spoken account to the relevant sales activity. The timing is deliberate. Capturing the debrief immediately after the interaction addresses the interval in which useful detail would otherwise be lost before entry.
aiola’s field-sales approach combines real-time, field-native voice capture with interpretation that can turn a single spoken input into an opportunity-stage update, a task, an activity log, competitive intelligence, and key contact data without requiring the rep to navigate an interface. Its fit rests on those capabilities, rather than on a general claim about transcription quality. Automation handles notes, follow-ups, and CRM sync at the point where the rep can still recall the interaction. The system is designed around someone physically present with customers.
Recording technique still has a role where meetings are recorded. Microphone positioning, background noise mitigation, and an external microphone for critical meetings are practical ways to improve the audio input. They complement field-ready architecture. Conversation intelligence can remain the layer for post-call analysis, while field-native capture addresses the information and actions that originate away from the desk.